How to Enforce Purpose Limitation in a GDPR-Compliant AI Pipeline
Purpose limitation under GDPR sounds like a paperwork requirement: write down why you're collecting data, and don't use it for anything else without asking again. In an AI pipeline, that principle turns into an engineering problem, because the whole point of a trained model is to generalize past its original context. This piece walks through what it actually takes to keep an AI system inside the purpose boundary Article 5(1)(b) draws, from the moment data enters a pipeline to the moment a model produces an output, and what regulators have said about it as of 2026.
Article 5(1)(b) sets up two obligations that get treated as one and shouldn't be. The first is specification: purposes must be spelled out at collection, explicit and legitimate, not written as a vague category. The second is a constraint on everything that happens afterward. A Record of Processing Activity that says "fraud prevention for card transactions" clears the bar. One that says "security purposes" does not, because it gives a controller too much room to justify almost anything after the fact. Applied to AI, this means a model trained on personal data stays bound to the purpose that data was collected for. It does not get to serve whatever purpose a product team discovers is convenient six months later.
The specific function creep problem GDPR did not originally anticipate in AI pipelines
Most software architecture treats data as a kind of shared utility: collect it once, and let any program or model that needs it draw from the same pool. That mental model is efficient, and GDPR was written to prevent it. The trouble is that most AI pipelines are built on that efficient, prohibited assumption without anyone quite deciding to build them that way. A training pipeline doesn't ask what a dataset was collected for before ingesting it; it asks whether the data is useful and well-formatted.
Data protection oversight bodies have pointed at this directly, identifying function creep as a significant AI risk under GDPR: a model trained for one purpose gets deployed somewhere incompatible with that original purpose, and nobody along the way treated that shift as requiring a fresh legal basis. Concrete cases make the abstraction easier to grip. An LLM trained on customer service logs to help resolve technical support tickets cannot turn around and get used for marketing profiling of the same customers, not without new, explicit consent covering that use. Data collected specifically for fraud detection cannot silently start feeding a predictive model for customer lifetime value, either, unless someone runs a compatibility assessment first or goes back for consent.
Repurposing isn't only about swapping datasets. Changing the computational task itself, or redefining what a model is being asked to do, can amount to repurposing under this framework even when the underlying data never moves. The dataset can stay bolted in place. The purpose still shifted underneath it.
The Article 6(4) compatibility test: what controllers must do before reusing data in a new AI context
Article 6(4) governs whether a controller can reuse personal data for a new AI purpose without going back to the data subject. It requires assessing how closely the new purpose relates to the original one, the context in which the data was first collected, the nature of the data itself, what consequences the new use might have for the person it describes, and what safeguards are already in place.
If the original legal basis for collecting the data was consent, the compatibility assessment is not available as an escape hatch, and this limit on when the test applies matters more than the test's mechanics. If the original legal basis for collecting the data was consent, the compatibility assessment is not available as an escape hatch. New consent is required, full stop. The test only helps controllers who relied on a different legal basis to begin with, like legitimate interest or contractual necessity.
France's CNIL has taken a firm position on how this plays out operationally: any controller authorization for repurposing data has to be granted case-by-case, weighing the specific purpose and the specific characteristics of the data in question. CNIL's reasoning suggests a processor that wants to reuse data for marketing would have a hard time clearing that bar, because marketing is rarely compatible with whatever narrower purpose the data was originally collected for. What triggers the test in practice lines up with the function creep discussion above: switching a computational task from recommendation to classification, changing what variable a model is trying to predict, or making algorithm-level changes to a computing system even while keeping the same task label on the box.
EDPB Opinion 28/2024's requirements for controllers
The EDPB adopted Opinion 28/2024 in December 2024. It stands as one of the most comprehensive statements this body has produced on how GDPR applies across the AI lifecycle, development through deployment through ongoing operation.
Four requirements come out of it that controllers can act on directly. First, processing purposes need to be defined with real precision, and AI outputs need to stay strictly aligned with those purposes. The opinion calls out scope creep and secondary uses incompatible with the original legal basis by name, not as a hypothetical risk but as the thing controllers are expected to actively prevent. Second, data protection assessments of this kind need to be thorough and documented, and they need to look past the obvious risks toward systemic and downstream harms, the kind that become visible only after a model has been in production for a while. Third, data quality and relevance need attention across the entire lifecycle, with minimization, anonymization, or pseudonymization applied wherever it's feasible to apply them. Fourth, governance needs actual structure: human oversight and continuous monitoring on an ongoing basis.
On legitimate interest specifically, the EDPB asks for a three-step assessment, and the mitigating measures a controller puts in place have to be tailored to the specific model and its intended use. Generic legal compliance measures don't satisfy this. The opinion says so explicitly: doing the legal minimum is not the same as doing enough for legitimate interest to hold up as a basis.
Best-practice guidance from another data protection oversight body adds detail: it calls for purposes to be defined explicitly at each phase of the AI lifecycle, not just once at the start. It calls for purposes to be defined explicitly at each phase of the AI lifecycle. It pushes minimization through curated, high-quality datasets, and synthetic or anonymized data wherever that's workable instead of raw personal data by default. And it asks for transparency toward individuals in interactive systems, meaning people should have some visibility into what a system is doing with their data when they're actively engaging with it.
The EU AI Act and Digital Omnibus's reshaping of the compliance picture as of 2026
Two separate laws now govern the same pipeline, and they don't overlap perfectly. GDPR governs how personal data gets handled. The AI Act governs the AI system itself, whether or not personal data is involved. Where a system processes personal data, and most consumer-facing AI systems do, both regimes apply at the same time, and a controller has to satisfy both.
The AI Act's rollout has been staged, and the schedule has already shifted once. Prohibited AI systems and AI literacy obligations came into force February 2, 2025. General-purpose AI model transparency requirements followed on August 2, 2025. The original deadline for full high-risk AI system compliance was August 2, 2026. But the Digital Omnibus, Regulation (EU) 2026/1744, passed in July 2026 and pushed that timeline back: Annex III high-risk obligations now land December 2, 2027, and Annex I obligations land August 2, 2028. Enforcement actions under the AI Act had been limited in the period following its rollout. A framework with no enforcement record yet is still a framework companies need to build toward, just without the deterrent effect that comes from watching someone else get fined.
The Digital Omnibus matters for purpose limitation specifically because of what it does to legitimate interest as a legal basis for AI training. Before November 2025, relying on legitimate interest to train a model was legally shaky ground, uncertain enough that a lot of controllers avoided it. The proposed reform would explicitly recognize legitimate interest as a valid basis for AI training, provided real safeguards are attached. That amendment is still sitting in Council negotiation as of this writing and hasn't been enacted, so nothing has actually changed yet on paper. But the direction is clear enough that pipelines can start being designed around it: pseudonymization as a technical safeguard robust enough to support a legitimate interest claim, rather than consent as the only workable path to training data. The safeguards need to be real controls with technical teeth.
Enforcing purpose limitation at the data collection and ingestion stage
The data protection by design principle requires technical measures from the earliest point in the pipeline and produces the standard against which later retrofits are judged. It requires technical measures from the earliest point in the pipeline, not bolted on after a model is already in production. Retrofitting purpose controls onto a live system is possible, but it's slower and leaves more gaps than building them in at ingestion.
The practical version of this is metadata tagging at the point of entry. Every record coming into a pipeline needs owner, source, freshness, sensitivity, and approved-purpose metadata attached to it before it goes anywhere else. This sounds like overhead, and it is, but it's the foundation every downstream control in this piece depends on. Without it, there's no way to check later whether a given record is allowed to be in a given training run.
What that metadata actually needs to capture: which purposes a record is approved for, which users and systems are permitted to touch it, retention limits and the conditions that trigger deletion, and provenance markers that satisfy AI Act requirements alongside the GDPR sensitivity classification. Automated tooling has increasingly been applied to scan newly ingested data and generate these tags: sensitivity for GDPR purposes, provenance for AI Act purposes, quality flags for the data science team. That automation matters less as a novelty and more as a fix for a specific failure mode, which is that manual tagging gets skipped under deadline pressure, and skipped tags are exactly where purpose limitation quietly breaks down.
Keeping purpose boundaries intact through model training
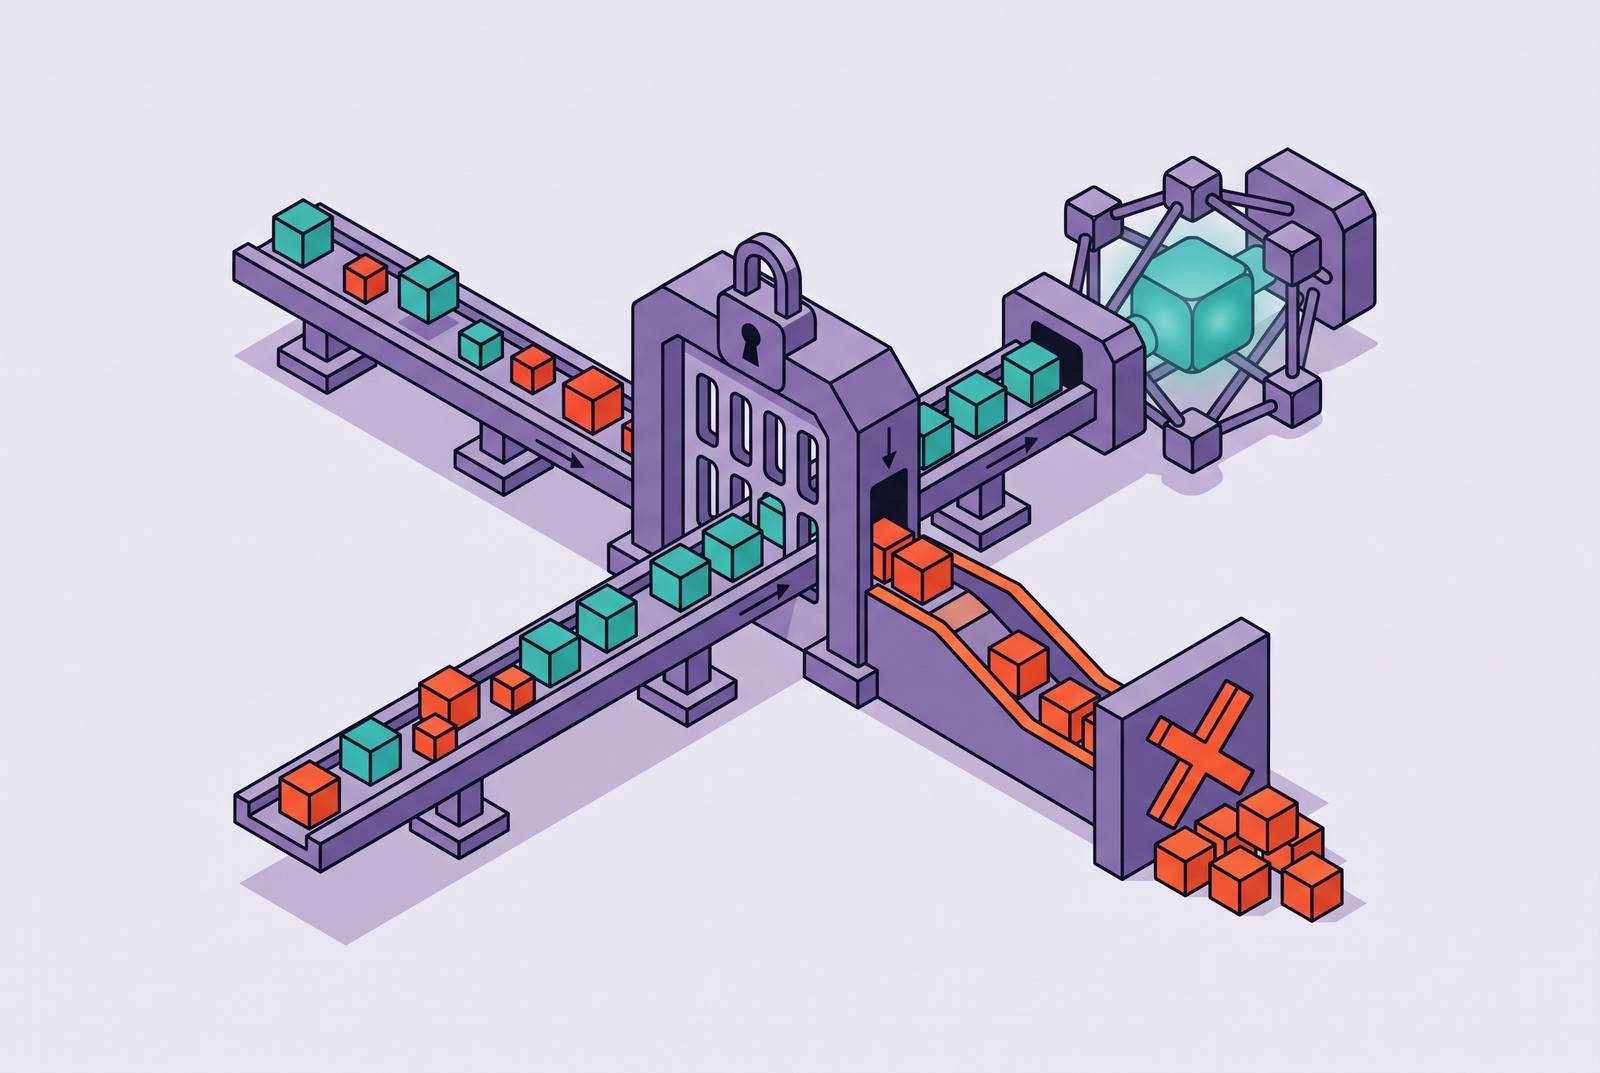
"Do Not Train" needs to be an architectural fact, not a policy sentence sitting in a contract somewhere. If a "do not train" tag exists on a record but the training pipeline can still physically read that record, the tag has done nothing. Real enforcement means the data never reaches the training process in the first place, blocked at the system level before a model ever sees it.
This clause is becoming standard in enterprise AI vendor contracts, which is a good sign for accountability but means little without the underlying pipeline actually implementing it, for individual users and enterprise clients alike, under whatever contractual terms apply to them.
Data lineage matters just as much. The traditional roles of data owner and data steward, long established in regular data governance, need to extend explicitly into data science workflows: covering not just first-party data but third-party datasets and synthetic data brought in from elsewhere. That requires clear standards and metadata that's actually accurate, plus active stewardship rather than a document someone writes after the training run is already finished. Adoption of unified data and analytics governance platforms has been growing across large enterprises. Organizations without lineage tracking into their training pipelines cannot prove what data trained what model, leaving them behind on that specific compliance question.
Enforcing purpose limitation at inference and output
A model built for one purpose can become a new processing activity the moment its inference context shifts. A support model queried at training time only for technical troubleshooting becomes something else entirely if it's later queried to profile the same users for marketing purposes. What matters here isn't only what's baked into the model's weights. Just as important is what the model is asked to do with personal data when someone runs a query against it, since that runtime activity needs its own lawful basis, separate from whatever justified training.
Access controls at inference time follow the same logic that governs training access. Role-based policies need to gate which users and systems can submit which categories of queries, extending the same governance model that protects a training set out to the inference endpoints where the model actually gets used day to day.
LLMs can memorize fragments of their training data and return them verbatim at inference, things like email addresses or other personal details showing up in an output where they were never supposed to appear. That's not a hypothetical edge case; it's a documented failure mode of large language models, and when it happens it's both a purpose limitation violation and a data minimization failure at the same time, exposing the deploying organization to liability on two fronts from one leak.
Article 22 GDPR adds a separate layer of restriction around automated decisions specifically. Decisions based solely on automated processing that produce legal or similarly significant effects on a person face real limits: an AI system generally cannot make such decisionsct a loan application, set an insurance premium, or screen a job candidate on its own, purely through automated processing, unless a specific exception applies, like contractual necessity, a legal authorization, or explicit consent from the person affected.
Third-party processors and vendor contracts as a purpose limitation control point
Feeding user data into a third-party AI API makes that vendor a processor, and Data Processing Agreements are required with each one. The enterprise deploying the system stays the controller throughout. It keeps the liability even when a processor is the one that actually mishandles the data.
CNIL's case-by-case principle applies here just as much as it applies to internal repurposing. A controller's authorization for a processor to reuse data has to be specific to a purpose and to the data's characteristics. A DPA that broadly lets a vendor use customer data "to improve the model" doesn't meet that bar, because it isn't tied to anything specific enough to assess for compatibility.
Evaluating a vendor through this lens raises a few concrete questions to ask before signing anything. Does the vendor offer regional hosting or data residency options that keep data inside the jurisdiction it was collected in? Are retention policies actually configurable, are access controls role-based, and can data flows be audited end to end? Is it possible to trace where data goes and how the system arrives at a decision, or is the architecture opaque by design? And does the vendor commit, in the contract itself, to Do Not Train controls for enterprise clients, not just as a marketing claim but as an enforceable term?
Privacy by design is turning into a genuine vendor selection criterion rather than a nice-to-have. Enterprises evaluating AI vendors are increasingly consolidating around a smaller number of platforms that treat data residency, access controls, and audit logging as baseline features built into the product, not premium add-ons sold separately. That shift says something about where the market is heading: purpose limitation compliance is becoming a product feature that vendors compete on, rather than a compliance burden buyers have to work around after the fact.