RATS Architecture and Attestation Evidence Formats
How role separation and standardized formats prevent devices from vouching for themselves.
A device that asserts its own trustworthiness is reporting on itself, and no self-report can be independently verified by the entity giving it. A signed measurement proves that a particular key produced that record. It does not prove what the software behind the key actually was, which is the entire question a remote party needs answered before it extends trust. A July 2026 paper on hardware-rooted AI-agent attestation puts it with unusual precision: "the signature proves the record was produced by a key the runtime holds; it does not prove what the runtime was". The same paper reaches for an aviation comparison that clarifies the stakes: a crew-written logbook can be honest and tamper-evident, and its trustworthiness still traces back to the operator who wrote it, so what the system actually needs is a manufacturer-sealed flight recorder whose provenance never passes through the crew's hands.
This is not a defect confined to one bad implementation or one careless vendor. Any runtime asked to assert its own integrity runs into the identical wall, because the asserting party and the party being assessed are the same party wearing two hats. The problem intensifies as systems grow more heterogeneous: cloud servers now run separate attestation environments for CPU and GPU, AI inference stacks assert their own model versions as part of their output, and IoT deployments must somehow carry attestation claims over channels built for a few bytes of sensor data rather than trust decisions. A reader might reasonably ask what would even count as "outside judgment" in a system where the hardware, the software, and the reporting mechanism all live on the same board. That question is the one the rest of this piece tries to answer, starting with the architectural response that the IETF's Remote ATtestation ProcedureS working group settled on.
How RFC 9334 breaks circularity by separating roles
RFC 9334 explicitly allows both models to run simultaneously on the same device for different purposes, since topology is not a global configuration but a per-interaction choice. The document defines five named roles, each with a distinct function.
The Attester produces Evidence about its own hardware and software state, typically something like a signed quote over platform measurement registers, with the signature rooted in a hardware component the Attester does not control at the software layer. The Verifier appraises Evidence against Reference Values and Endorsements, then emits Attestation Results; its judgment does not depend on anything the Attester itself claims about its own trustworthiness. The Relying Party sits downstream of the Verifier and consumes only the Attestation Results, making the actual trust decision, such as granting network access or releasing a key, without ever appraising raw Evidence itself. Supply-side roles make the Verifier's appraisal possible in the first place: the Endorser, typically a hardware manufacturer, supplies Endorsements that help the Verifier establish the authenticity of the Attester's signing keys and capabilities, and the Reference Value Provider, typically a manufacturer or supply-chain actor, supplies the known-good measurements against which Evidence is compared.
An Attester cannot make a measurement true by signing it; signing only proves custody of a key, while the Verifier's appraisal is a separate act, grounded in Reference Values and Endorsements the Attester never touches. A Relying Party is no longer being asked to trust a device's own software. It is trusting the Verifier's appraisal, and that appraisal in turn rests on hardware-vendor Endorsements and supply-chain Reference Values that sit entirely outside the Attester's reach. This just moves the circularity onto the Verifier and its inputs. It does, but the Verifier's inputs come from parties, manufacturers and supply-chain actors, who have no stake in a particular Attester's outcome on a particular day, which is a meaningfully different position than asking a device to vouch for itself.
The Passport and Background-Check topologies as concrete data flows
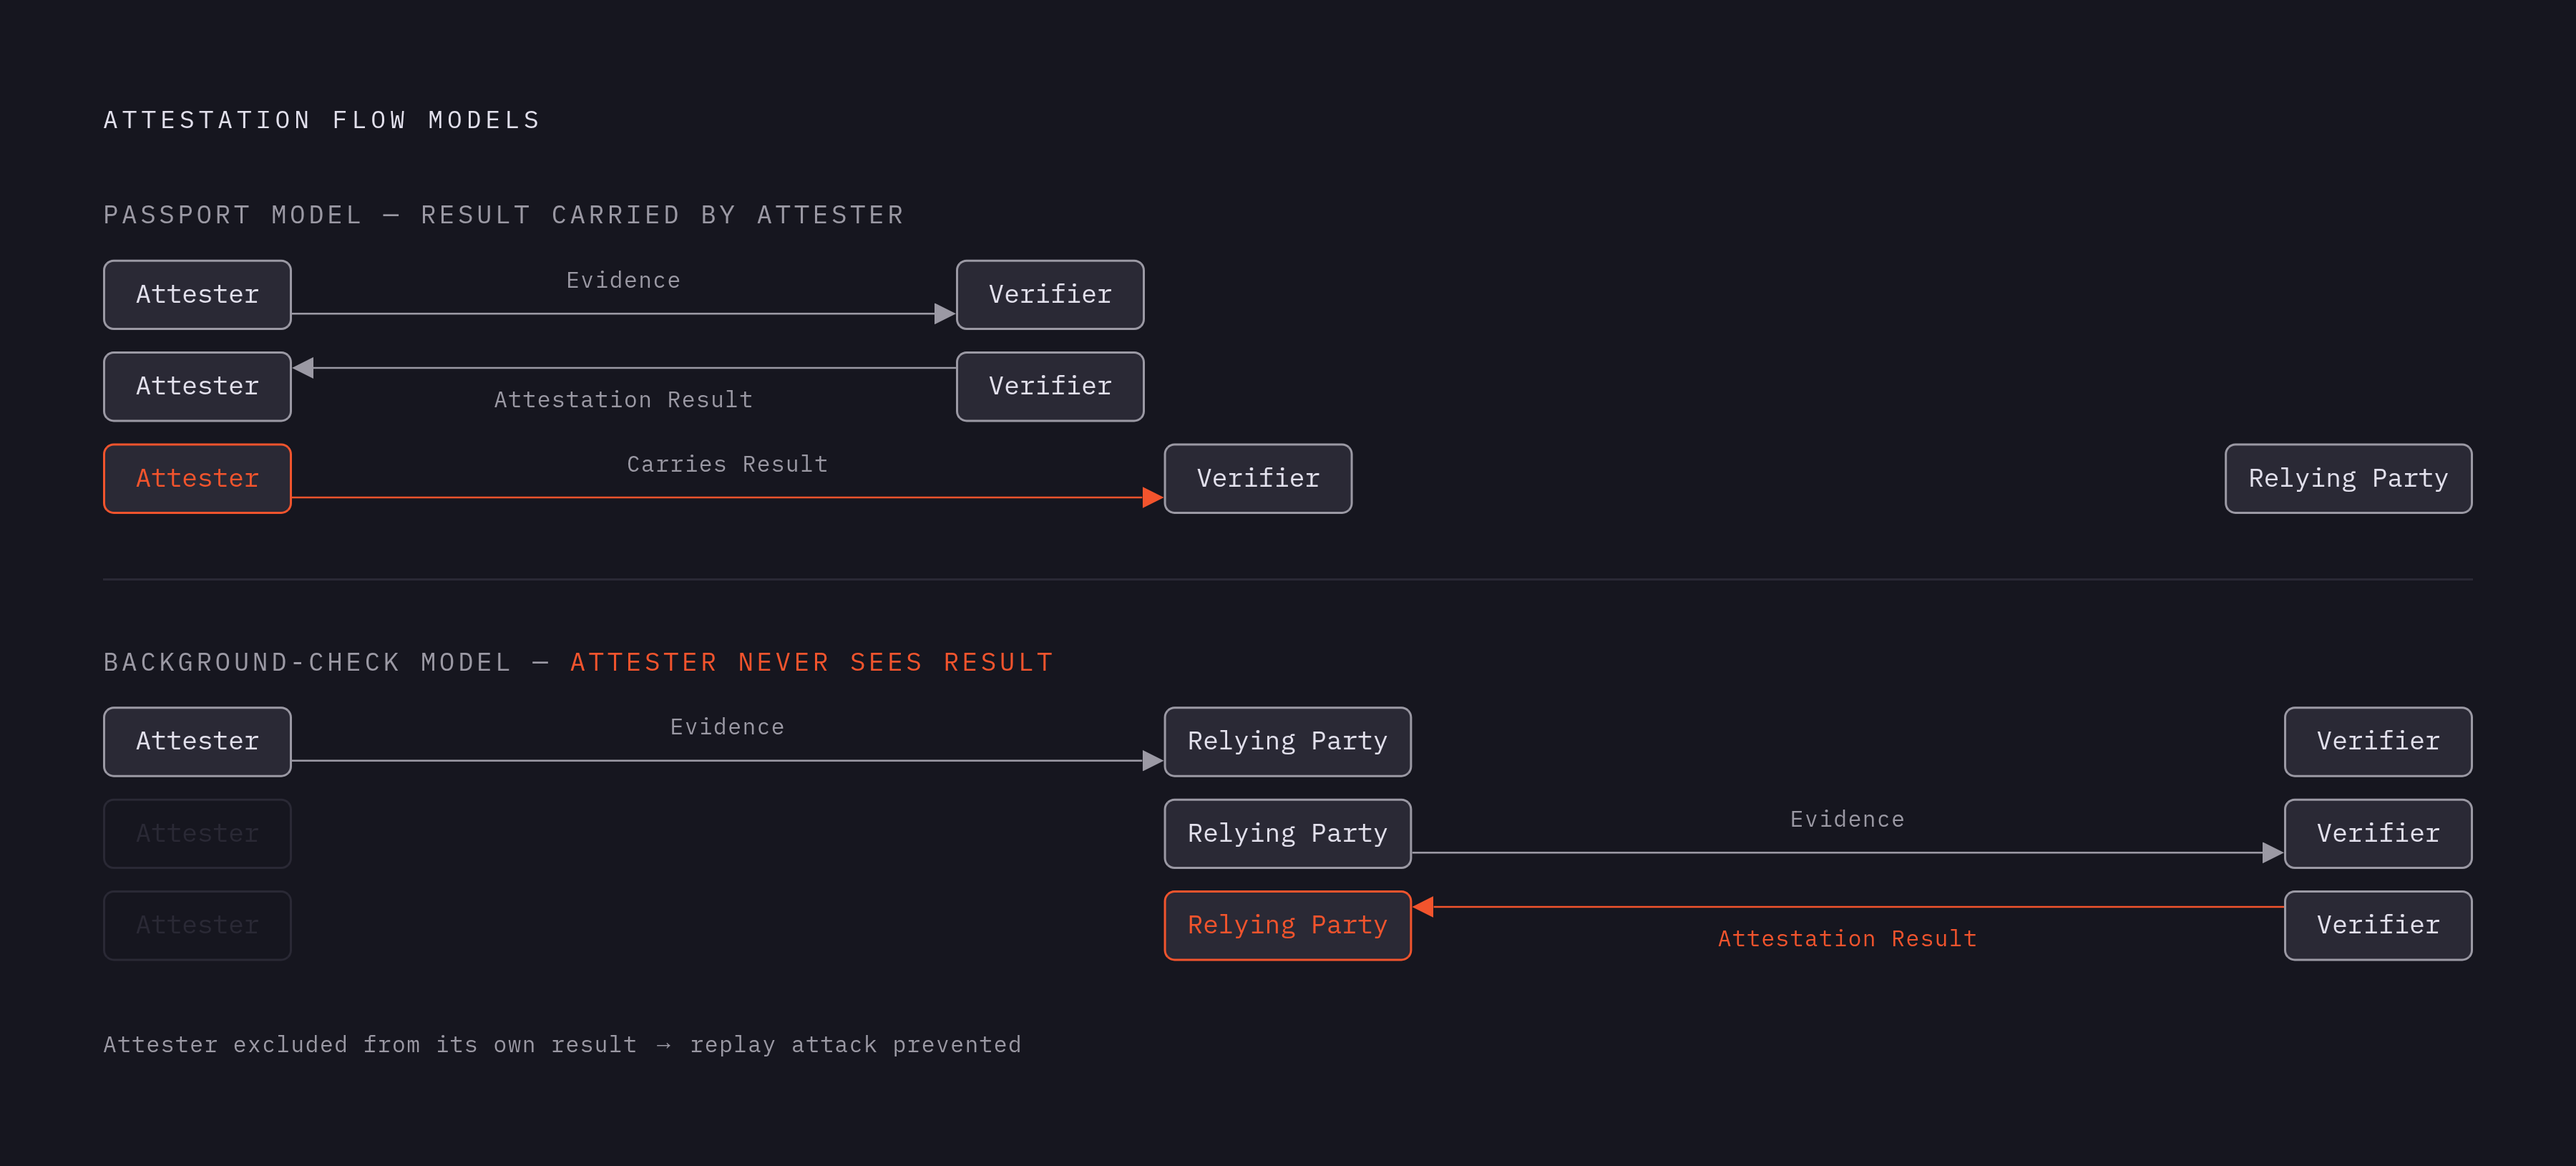
Role separation describes who does what, but it does not by itself describe who talks to whom, and in what order. The same five roles connect differently depending on whether the Attester or the Relying Party initiates the appraisal chain, and the choice carries real privacy and operational consequences.
In the Passport Model, the Attester presents Evidence directly to the Verifier, and the Verifier returns an Attestation Result that the Attester then carries as opaque data. The Relying Party only ever sees that carried result; it never touches the raw Evidence that produced it. The practical advantage is that an Attester can obtain its result while offline and reuse it across many subsequent interactions, which keeps the Relying Party's side of the exchange lightweight.
The Background-Check Model reverses the direction of the first two legs. The Attester sends Evidence to the Relying Party, and the Relying Party, not the Attester, forwards that Evidence on to the Verifier. The Verifier then sends its Attestation Results directly back to the Relying Party rather than to the Attester. This ordering buys freshness: because the Relying Party initiates the appraisal at the moment it needs a decision, the result is current relative to that specific request, and an Attester has no way to pre-compute a favorable result and replay it later. The Attester never sees its own Attestation Result in this model, which matters in deployments where the Attester should not be able to learn, let alone influence, how it was judged.
Neither topology is universally correct, and RFC 9334 does not force a device to pick one. The format carrying Evidence and Results has to work the same way regardless of which direction the messages are flowing: the Verifier appraises Evidence against Reference Values and Endorsements and then emits Attestation Results, independent of the Attester's assertion.
Role boundaries and evidence format standardization
Role separation is an architectural promise, and promises on paper do not enforce themselves. A Verifier that cannot parse or semantically interpret an Attester's Evidence cannot appraise it, no matter how cleanly role separation is defined on paper. The boundary between Attester and Verifier only holds if the thing crossing that boundary, the Evidence itself, means the same thing on both sides.
That is harder than it sounds, because Evidence structures differ across hardware platforms and vendors, and a Verifier has to understand both the encoding and the underlying semantics before it can judge anything. When formats diverge, a Verifier is forced to translate incoming Evidence into some internal representation, and that translation step is exactly where original claims can get silently dropped or misread. Open-source remote attestation tools have developed independently of one another, producing real inconsistency in how attestation data gets formatted and exchanged, and this undermines interoperability across every Verifier, Relying Party, and Attester trying to work together.
The format ecosystem that has grown up around RATS exists specifically to close that gap, and each format targets a specific boundary in the role diagram rather than trying to be a universal container. EAT carries Evidence from the Attester toward the Verifier. CoRIM carries Reference Values and Endorsements from supply-chain actors toward the Verifier. CMW envelopes any conceptual message across any transport leg, regardless of direction. EAR carries Attestation Results from the Verifier toward the Relying Party.
EAT: how the Attester's claims reach the Verifier
EAT is the format doing the heaviest lifting at the first boundary, the one between Attester and Verifier. It takes a hardware measurement and turns it into a structured, machine-readable claim that a Verifier can actually appraise rather than merely receive. The format is specified in RFC 9711, which reached Proposed Standard status in 2025, and it functions as the principal token format across the RATS ecosystem.
Structurally, an EAT is either a CBOR Web Token or a JSON Web Token, extended with claims specific to attestation. An EAT can describe the state and characteristics of almost any entity capable of producing a signed measurement, from a smartphone to an IoT sensor to a piece of network equipment.
The CWT path is not a stylistic alternative to JWT so much as a response to a hard constraint. The CWT path is designed for constrained environments where bandwidth is severely limited; a LoRaWAN uplink at SF12 carries very little payload per message, so CBOR-encoded EATs must remain very compact for in-band transmission. The July 2026 AI-agent attestation paper uses a TPM-based, attestation-key-signed quote as the hardware Evidence in its composite attestation experiment, folding the hash of a software Action Evidence Package outcome along with a fresh appraiser nonce into that signed quote. CWT exists as a distinct path because of the bandwidth constraint, rather than JWT simply being extended to cover every deployment.
CoRIM and CoMID: how supply-chain actors give the Verifier something to compare against
EAT solves the problem of getting Evidence from an Attester to a Verifier in a form the Verifier can read. It does not solve the separate problem of what the Verifier is supposed to compare that Evidence against. Without a standardized format for Reference Values and Endorsements, a Verifier has no authoritative notion of "known-good" to measure incoming Evidence by, and CoRIM, together with its CoMID building block, is what supplies that anchor.
CoRIM, the Concise Reference Integrity Manifest, remains an active Internet-Draft rather than a published RFC. The profile mechanism is what lets this stay a shared format rather than fragmenting into vendor dialects: a base CoRIM definition can be extended for a specific Attester's quirks without abandoning the common model everyone else relies on.
CoRIM carries Reference Values and Endorsements from supply-chain actors toward the Verifier, which uses them alongside Evidence to assess the trustworthiness of the Attester.
CMW: the envelope that keeps heterogeneous formats interoperable across transport legs
EAT and CoRIM solve two different problems on two different sides of the Verifier. Neither says anything about how a message physically travels from one role to another, across protocols that were never designed with attestation in mind. That is the gap CMW, the RATS Conceptual Messages Wrapper, closes. The specification is draft-ietf-rats-msg-wrap-18, published September 2025 on the Standards Track, and it defines a dedicated CBOR tag, matching JWT and CWT claims, and an X.509 extension, so the same wrapped message can appear inside CBOR-based protocols, web APIs, or PKIX certificates without redesign. It also defines a media type and a CoAP content format, extending its reach to HTTP, MIME, and CoAP transport.
The practical payoff is that serialization formats can keep evolving without breaking the protocol layer underneath them, because a Verifier or Relying Party can tell what kind of conceptual message it is holding before it ever attempts to parse the contents. In the Background-Check topology, Evidence flows Attester to Relying Party and then Relying Party to Verifier across separate protocol paths. CMW is what lets both legs of that journey carry the same payload without each protocol separately inventing its own attestation framing. CMW does not care what format it is wrapping. It envelopes EAT, CoRIM-based material, DICE evidence, SPDM measurement blocks, or Attestation Results with equal facility. That is its entire job, and it is a narrower job than EAT's or CoRIM's: CMW carries no semantics of its own, it just makes sure the semantics carried by other formats survive the trip.
Attestation Results formats: the still-maturing output side of the Verifier
Evidence and Reference Values both have mature, purpose-built carriers in EAT and CoRIM. The output side of the Verifier, the Attestation Results that a Relying Party actually bases its trust decision on, does not yet have the same settled vocabulary. RFC 9334 defines Attestation Results as a conceptual message, but it deliberately specifies no wire format for them, leaving a gap at precisely the boundary where the trust decision gets made.
That asymmetry is not a minor gap in an otherwise finished picture. The Evidence side of the Verifier has more standardized carriers available to it than the Results side does, and the consequence falls on Relying Parties, who end up depending on proprietary or pre-standard vocabularies for the one output that actually determines what happens next. A Relying Party can receive Evidence that was produced, carried, and compared against Reference Values using fully specified formats at every step, and still end up acting on a Results message whose shape was never standardized at all.
Two Internet-Drafts are underway to close that gap. Attestation Results for Secure Interactions, known as AR4SI, defines a vocabulary that lets a Relying Party act on what a Verifier has told it, giving some structure to the decision layer that RFC 9334 left conceptual. The role separation that RFC 9334 establishes, and that Passport and Background-Check topologies both depend on, is only as strong as the weakest format standing at any one of its boundaries. Right now, that weakest point sits exactly where the Relying Party has to act.
Sources
- RFC 9334: Remote ATtestation procedureS (RATS) Architecture
- Hardware-rooted attestation for AI-agent evidence: composing IETF RATS with action evidence packages
- draft-ietf-rats-msg-wrap-18
- Attestation Results for Secure Interactions
- RFC 9711 - The Entity Attestation Token (EAT)
- draft-ietf-rats-corim-11 - Concise Reference Integrity Manifest